The recent abrupt departure of the MIT admissions dean provokes many thoughts, some silly ("Not the type of admissions she was supposed to make!") to the serious. But one thing which it certainly underlines is the limits of degrees as indicators of ability.
I by no means condone Marilee Jones' resume stretching. I remember near thermonuclear conditions when once someone nonchalantly described a third party's intent to obtain an advanced degree (I think it was a doctorate) through a mail order college. I worked hard for that sheepskin! I sacrificed! I suffered! Thou shalt not claim degrees in vain!
But, degrees have at least two relevant properties. First, they are a symbol of hard work and achievement. Second, they are proxies for ability and knowledge when attempting to hire someone. Ms. Jones never did the work or made the achievement, but she certainly demonstrated the aptitude to carry out her position. She was apparently widely recognized as a leader in her field.
It is less common than it once was, but some companies still require certain degrees for certain positions. In some cases this is completely defensible (could you take seriously a medical director lacking a medical degree?) and perhaps even legally mandated (is there any position that legally requires a Ph.D.?), but too often this is the lazy way out of real thinking. Degrees are important, but the level of effort invested varies. There are many talented persons who are perfectly capable of earning an advanced degree, but for one circumstance or another never did -- and some of them have gone on to Nobel Prizes. On the flip side, there are persons who no longer exhibit the qualities of a Ph.D. or M.D. -- persons who make you wonder how they got there in the first place. Even persons brilliant in one area can be completely off the rails in many others -- e.g. William Shockley.
I believe that one mark of an intelligent organization is an ability to look beyond paper qualifications and look at real achievement. My previous company had an ongoing tradition of this. When the big sequencing center was being set up, they didn't demand a Ph.D. but rather handed the job to someone who had shown previously (in academia) the ability to get things done -- he did & went on to found a successful genomics company (Orion). Even near the end of my tenure there were research associates being promoted to Ph.D. level titles ("Scientist"), because they had demonstrated the creative thinking and scientific leadership which are the true requirements of that grade, not the piece of paper.
Hiring people is hard & sucks up lots of time. Degrees are a useful shortcut, but one should never forget that shortcuts aren't always the best idea.
Saturday, April 28, 2007


Thursday, April 26, 2007
(Still)Birth of a Neologism?
A proposal has been published in the open access journal Molecular Systems Biology for a new term, or really family of terms, for various elements of genetic information.
First they propose a whole host of types of genes. For example, a protein coding gene is a P-gene and these are further subdivided into structural protein genes (sP-genes) and regulatory protein genes (rP-genes). A cynic might point out there are already proteins refusing to choose sides, such as transcription factors with enzymatic activities (I know I've come across them, but alas memory is failing to return their names). Actually, they already lump the proteasome subunits into the P-gene class (subclass 4). Are indirect regulators of transcription (e.g. IkB and IKK, which regulate the transcription factor NFkB) in here too?
RNAs in this taxonomy come in two basic flavors: structural (sR-genes) and regulatory (cR-genes) c=control? cR-genes are subdivided into discriminating (regulating specific genetic subprograms; e.g. miRNAs or XIST) and non-discriminating (broadly acting; e.g. tRNAs and snoRNAs).
There's more. For all of the cis-acting elements controlling a gene are its 'genon' and the trans acting factors the 'transgenon'. We also have pre-genons, holo-genons, proto-genons, holo-transgenons.
In any complicated endeavor jargon is inevitable, as complex topics can't be explained in detail every time you go to talk about them -- rather, the jargon serves as a shorthand to enable actually getting something done. Attempting to generate such taxonomies is useful, but it's hard to think of much success in that department. This exercise is reminiscent of Brosius & Gould's attempt to create a nomenclature for pseudogenes. Very clever, but it never caught on.
A cynical pedant might be inclined to ask "what's the point of inventing new jargon when nobody can be bothered to properly use the old jargon". For example, periodically the popular press (and sometimes new iMedia of blogs) trumpet the discovery of a new human gene, which might be a bit disconcerting to various taxpayers who thought they had paid to have them all found already. While there are almost certainly some new genes to be found, in most cases what is new is an association of alleles with disease, and in these SNP-saturated times even the alleles can't claim to be new. Too often also is the overuse of 'gene' when the more specific 'locus' would do, or gene where 'gene product' or 'protein' would be a better fit. And other times, not only was there no discovery of a new gene, but the phenotypic association was linked only to a large stretch of DNA.
One speculation this all leads to is what does drive the acceptance or non-acceptance of new terms, particularly ones intended to be pronouncable (nobody, other than the once extant company, tries to read siRNA as two syllables!). 'omes and 'somes seem to have a better bet than some terms, but I'm sure there's been duds for that (and of course, words that didn't enter the language by that route -- do I really live in the collection of all things beginning with the letter 'h'?). Some good terms rise & fall, or only survive through their derivatives. Virtually nobody talks about a cistron, but polycistronic survives -- a pity, since cistron is a perfectly wieldy word -- luckily I can stay gruntled without solving the mystery.
Gobble Gobble Slurp
AstraZeneca's record-setting $15B+ buy of Medimmune gave the old workplace's stock a mild goose, but things have settled. It is a reminder of what the ultimate fate of virtually any semi-successful biotech company will be.
In the end, there are three possible fates for a biotech: survival, liquidation or acquisition. Liquidation is rare & will probably always happen to early-stage companies, but does happen. One genomics company (Progenitor) reputedly let their employees show up for work to locked doors. Most companies will be acquired down the road; only a few frontrunners will stay independent. There are, of course, variations on these themes. J&J has a track record of acquiring companies but then leaving them largely recognizable. Some companies (e.g. Cadus) disappear in an operational sense but never quite disappear legally -- business zombies. Mergers of equals are theoretically possible and often claimed (Biogen-Idec), but how lopsided the division of spoils is can't really be assessed by an outsider.
Millennium executed a number of acquisitions during my tenure, with many being quite successful -- influential people remain who joined through the Chemgenics or Leukosite acquisition. Leukosite brought in Velcade (then PS-341), from a company (Proscript) which Leukosite hadn't finished digesting (er, assimilating) when the the MLNM-LKST merger was announced. Much of Millennium's inflammation pipeline has strong roots back to Leukosite.
But then there was the big demonstration of 2+2<<4: COR. Millennium bought COR for Integrillin & a sales force, with some interesting early stage oncology and cardiovascular programs in as icing. The corporate cultures seemed compatible and the excitement was there. But somehow things quickly ran downhill & when it became apparent that Millennium was overstretched, the COR (now MLNM San Francisco) site was targeted for liquidation. Eventually, after sinking many dineros into further clinical studies, Millennium essentially walked away from Integrillin. So for $2B plus, a sales force was purchased plus a revenue stream from Integrillin and some other leftovers -- plus some important contributions from the ex-COR folks in wrapping up the Bayer collaboration. Was it worth it? My impression is that everybody on the COR side wished they could get a do-over.
MedImmune was hardly an isolated purchase -- big pharmas and even big biotechs (Amgen, Genentech) have been plucking out various biotechs, generally either for hot therapeutic platforms (siRNAs, advanced antibody technologies or exotic antibody alternatives) or late stage compounds. Looking around the Cambridge neighborhoods finds plenty of companies in the former (Dyax, Alnylam, Archemix) or latter (MLNM, Vertex, Alkermes) categories. The majors still have their gaping pipeline gaps, and Wall Street is starting to hound Genentech towards more acquisitions -- and Amgen is starting to experience the pain of commercial reversals. Odds are there will be more buyouts -- and more flameouts & companies (e.g. Imclone) which flop at the auction bay.
So grab a ringside seat & get comfortable -- but please don't play the ponies. If anyone tells you they know who's going to buy whom for what price, odds are they're lying. Even if they aren't, do you really want to follow in the footsteps of the famed biotech investor who was wisked from her Connecticut home to a federally-paid stay in West Virginia?
Monday, April 23, 2007
A good RNAi guide
Cell Cycle is an interesting little journal that publishes many papers open access. A nice little review of the statistical treatment of genome-wide RNAi is available freely.
The review focuses on noise and variance in RNAi screens, and doesn't explore some of the other key issues such as off-target effects, interferon response and appropriate cell lines. So it isn't a complete guide but a sharply focused one.
A recent Nature has a paper on genome-wide RNAi for targets increasing sensitivity to the key antitumor agent paclitaxel (alas, not free).
Genome-wide RNAi with siRNAs is a powerful technology, but it requires a pretty large investment in automation to make it work. That will slow the widespread adoption of the technology, which isn't entirely bad. In some ways, mRNA microarray technology spread too far too fast leading to many bad papers being published before the methodologies were well worked out. Of course, there are still lots of bad microarray papers being published, but you can't make the horse drink. Some bad papers have poor microarray analysis, and others are just atrocious experimental design. In the end, the technology has been besmirched, generally unfairly.
Nobel Betting
ChemBark proposes odds for next fall's Chemistry Nobel. Of course, a lot are really biology (prompting the usual grumbling from a small set of chemists). I would too argue along with one commenter that 'The Pill' would be more apt under Medicine (and would seem to be deserving given the impact on society).
One of those satisfying "I've really joined the fraternity" moments is when you start recognizing the names in the Nobel announcements as work you are familiar with. Of course, that doesn't mean it happens every October, but often enough that I'm still convinced I earned my stripes.
One of those satisfying "I've really joined the fraternity" moments is when you start recognizing the names in the Nobel announcements as work you are familiar with. Of course, that doesn't mean it happens every October, but often enough that I'm still convinced I earned my stripes.
Friday, April 13, 2007
Farewell Kilgore Trout
The passing this week of Kurt Vonnegut was strongly felt here, as he is one of my favorite authors. I first was keyed into Vonnegut by a high school English teacher (by the name of French!) and started reading a few. When I got to college, I started plowing through the whole shelf of Vonnegut novels & catching his few last ones as they came out. If you've never savored the ever-relevant bitter humor of Mother Night or the absurdity of Cat's Cradle, you're missing out. Breakfast of Champions & Sirens of Titan are great fun too, and even the lesser works have lots of good bits in them. Vonnegut isn't for prudes, though has texts are really pretty tame compared to a lot of other literature before and after (e.g., my current soul-enriching time sink, The Good Soldier Svejk -- now there is some inspired vulgarisms!)
Please don't take this the wrong way, but I enjoy reading good obituaries. Not that I'm happy to see someone pass, but good obituaries teach you something you didn't know -- perhaps because you never knew the person existed (but should have), but other times because you didn't know something interesting about a familiar figure. I never knew that Vonnegut had studied to be a biochemist. I think Asimov was also originally a biochemist as well -- but surely to group them in this way is to engage a granfalloon. Hi Ho!
Please don't take this the wrong way, but I enjoy reading good obituaries. Not that I'm happy to see someone pass, but good obituaries teach you something you didn't know -- perhaps because you never knew the person existed (but should have), but other times because you didn't know something interesting about a familiar figure. I never knew that Vonnegut had studied to be a biochemist. I think Asimov was also originally a biochemist as well -- but surely to group them in this way is to engage a granfalloon. Hi Ho!
Thursday, April 12, 2007
When a little fighting is good
Last week's Nature has a great paper in it that takes several readings before it makes sense. It's not that the paper is poorly written, it's just that the results take a while to burrow through a bunch of preconceptions.
The paper looks at the effects of combining two antibiotics which antagonize each others actions, primarily doxycycline and ciprofloxacin. What is interesting, and initially counter-intuitive, is that mixing the two antibiotics at low doses (all in culture) creates a very different selective environment than two antibiotics which show additive effects. If you look at the space of possible combinations, then if the antibiotics add a strain resistant to one of the antibiotics will always grow better than an otherwise identical strain which is sensitive to that antibiotic. However, if the antibiotics are antagonistic then there will be some combinations which favor growth (Figure 2). They go on to show that this theoretical analysis indeed holds true for mixed cultures (Figure 3).
The interesting possibility is that by dosing the two drugs appropriately, resistance mutations would be at a competitive disadvantage to their wild-type kin and would therefore not take over the population. The article is appropriately cautious in extrapolating these effects to clinical settings. This remains to be demonstrated in an animal setting, let alone a patient. But it is intriguing. In addition to some mouse experiments, an obvious next step would be a further exploration of whether resistance mutations do emerge in long-term cultures.
Even if the results were to get past such experiments, it is difficult to see this work escaping the economic trap which ensnares all antibiotic work. Any commercial activities must compete with cheap, highly effective existing antibiotics. Academics could try to develop such combinations, but the patients in true need of such drugs are desparately ill, making finding any clinical signal difficult.
However, this could be a very interesting strategy to explore for cancer. There are definitely examples of chemotherapy agents which conflict with each other. For example, topoisomerase inhibitors & bortezomib. Combinations using this strategy might be cytostatic -- aiming to keep the tumor in check -- but that could be sufficient in many settings. However, these bump against the challenge for any cytostatic chemotherapeutic agent: you can't use tumor shrinkage as a clinical measure but must measure survival. Survival is what really counts, but requires much longer and larger studies.
Wednesday, April 11, 2007
The ups-and-downs of out-licensing
Monday's Boston Globe had an interesting article (probably $$$) on a story which hadn't seen much attention previously but illustrated a number of biotech themes: rapid reversals & odd partnerships.
A group at Beth Israel Deaconess Medical Center (BIDMC) had developed a potential new protein therapeutic which they thought they might hit it big with. I must confess a special fondness of BIDMC, as a team there oversaw the delivery of my most important project ever, but they seem to have really gone out on a strange limb in this case by picking an odd partner for developing their blockbuster.
The potential blockbuster is apparently a single chain protein encoding a dimeric erythropoeitin (EPO). EPO is, of course, the most financially successful biotech drug ever and what made Amgen bigger in market cap than some old-line pharmaceutical companies. EPO has been in the crosshairs of a number of other companies, but Amgen has thus far won all the battles on patents -- first with Genetics Institute (now Wyeth) at the outset and later knocking out Transkaryotic's (now Shire) attempt to end-run their patents. Amgen followed up with a slightly modified form (Aranesp), which has also cleaned up. Affymax has a clever mimic in trials -- though this illustrates the need for patience in this business, as their splashy paper on it came out when I was interviewing at Millennium nearly 11 years ago!
So a tandem EPO would seem like a reasonable bet, with the claim that this form is longer lasting (ala Aranesp) and more potent. EPO is used to treat anemia in kidney failure (EPO is normally made in the kidney) and cancer patients (along with illicit off-label uses in the field of athletics) -- more is better, right?
Lately, the bloom is off that rose -- several studies are suggesting that for cancer patients there may be drawbacks to high EPO doses. EPO has now earned a black box warning and Amgen is scrambling (the CFO just bailed -- perhaps with shoeprints on his backside).
Now that's just bad luck -- pharmaceuticals are like that. One day COX2 inhibitors are miracle drugs; the next day they're persona non grata.
It's the other half of the story that I found very curious. If you were trying to out-license your institutions exciting new protein therapeutic, what would your first choice of company be? How about a failing genomics company with a slim bank account? No? That doesn't sound appealing? But that's exactly what BIDMC did.
Now a lot of genomics companies exited the genomics boom in a strange place: lots of money raised during the bubble, but no path forward to make money in genomics. Companies such as HGS and MLNM are still living off that cash, but they had interesting programs going. Others had stranger outcomes. Variagenics and Hyseq proved that 1 genomics company + 1 genomics company = 0 genomics companies, as they merged, ditched all their genomics operations, and changed to Nuvelo to develop an in-licensed protein therapeutic.
BIDMC chose DNA Print Genomics for their wonder drug. I have nothing against DNA Print, but there's nothing in memory (or on their website) to suggest that they have any of the key skills. Nor do they have much cash. While they do actually have products, those products don't inspire much awe. DNA Print will type your DNA to estimate your ancestry. That might be fun, but how big is the market really? They also claim to have tools which can predict the physical characteristics of a person (skin color, earlobe attachment) from forensic samples -- a sort of genetic sketch artist. I'm sure there are missing persons-type cases where this provides one more set of clues, but its hardly something that would see routine use in cases.
Wall Street hardly loves DNA Print -- if Yahoo's statistics are to be believed, it is trading at a market cap of 4.58M much below its cash position of about 8.5M -- but it is also (if I'm reading this right; I really don't stare at these often) blowing through 3-4M per quarter -- meaning that cash will run out in the near future unless they find financing or take a scythe to their operations. This was a point raised in the Globe article -- BIDMC has hitched their wagon to a lame horse which may expire very soon.
An interesting question, which one can never get a straight answer to, is why pick DNAPrint? Was there really nobody else interested? It is curious that the consultant who BIDMC hired to find a licensee (after Eli Lilly had bailed out) for the compound ended up as chief executive at DNAPrint. While that is hardly unheard of, it does raise a real issue of conflicts of interest. The deal structure is strongly loaded towards milestones & royalty payments -- i.e. BIDMC sees very little without a lot of progress being made. DNA Print apparently has reported preclinical results.
A weak & failing partner for a troubled market niche -- hardly a good place to be. C'est la biotechnologie!
Tuesday, April 10, 2007
N-A-I-V-E, on a double word score
Monday's Globe had a short article on an MIT junior who plays competitive Scrabble and has also devised a Scrabble-playing program called Quackle. What was striking was the confident pronouncements of some Scrabble experts that a computer would never be able to beat them; of course similar pronouncements have been heard for checkers, chess, etc.
One expert opines:
Another player makes the following analysis of a lookahead strategy
IMHO, these domain experts are falling into the easy trap for domain experts: that what works for humans can't be computerized, and conversely what doesn't work for humans won't work for a computer. Humans are terrible at comprehensive lookahead strategies, but computers can do them flawlessly -- given enough time and compute cycles. This is sometimes a difficult idea to get across to domain experts -- both game players and biologists -- that it is more important to describe what your problem is than what they are certain are the aspects the computer can't do. Maybe some pieces can't be solved -- but maybe those pieces can be bypassed instead.
Of course, it does depend on your metric. The same critic of lookahead also offered
On the other hand, who am I to talk. As an early exercise to learn Java I found a Reversi applet I could consistently beat & tried to improve its lookahead algorithm. Until I moved to more bioinformatic relevant problems, the program torture me -- because I could wallop my versions even harder than the one I started with! Any Hippocratic software oath of mine was badly violated!
One expert opines:
Quackle has the right name for sure, because the whole idea of using a computer to play Scrabble is a quack of an idea
Another player makes the following analysis of a lookahead strategy
you're wasting your time because there's too much randomness ahead of you
IMHO, these domain experts are falling into the easy trap for domain experts: that what works for humans can't be computerized, and conversely what doesn't work for humans won't work for a computer. Humans are terrible at comprehensive lookahead strategies, but computers can do them flawlessly -- given enough time and compute cycles. This is sometimes a difficult idea to get across to domain experts -- both game players and biologists -- that it is more important to describe what your problem is than what they are certain are the aspects the computer can't do. Maybe some pieces can't be solved -- but maybe those pieces can be bypassed instead.
Of course, it does depend on your metric. The same critic of lookahead also offered
There's enough luck in the game that it's not really possible for pure word knowledge to defeat a slightly less pure word knowledge every time. Now, for any game with a luck component it will be impossible for a program to win every time. I would agree with this -- and might even try (if I were doing this) to have the deeper levels of the lookahead use a much smaller dictionary (or more likely, some sort of word model along the lines of the word guessers in cell phones). The key isn't necessarily searching every possibility, but rather searching most of the most probable space.
On the other hand, who am I to talk. As an early exercise to learn Java I found a Reversi applet I could consistently beat & tried to improve its lookahead algorithm. Until I moved to more bioinformatic relevant problems, the program torture me -- because I could wallop my versions even harder than the one I started with! Any Hippocratic software oath of mine was badly violated!
Friday, April 06, 2007
woof WOOF!
I had offered to let the Omics! Omics ergonomics director scribe tonight's entry, since it covers a topic of which she has direct knowledge, but we ran into two problems. First, the keyboard is poorly engineered for the configuration of her digits. Second, she's too excited by the news to think straight. But, she did suggest the headline and sometimes that is the hardest part of all.
Dogs are amazing products of human selection. Size, color, shapes of various body parts, and even behaviors are distinctive to particular breeds. The size range of adult dogs exceeds that of any other mammal, as wonderfully illustrated by the
cover of Science, as the issue announces the IGF1 locus as the major determinant of size in dogs.
This paper also illustrates how science can be a bit slow to get off the ground. About 15 years ago I heard a seminar from the senior author of this paper discussing the great promise of dog genetics to shed light on important medical and biological questions. In the meantime, there really haven't been much in the way of splashy dog genetics papers, though the community has been slowly building up a cache of tools. I think it is a reasonable expectation that this paper will be the head end of a series of papers unleashing the promise of the field.
After all, consider my diminutive assistant.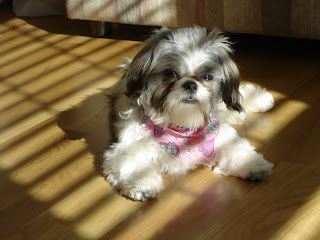 . If you line her up with a Scottish terrier, while they are about the same size they have little else in common in their basic shape. Amanda has the flat face characteristic of her tong (The Ancient and Honourable Order of the Shih Tzu), whereas the Scottie has a distinctive snout which marks his clan. Her tail could honestly mistaken for a feather duster, whereas the terrier's has a less severe curl and isn't fluffy. A Scottie has erect ears; a Shih Tzu's are floppy. Each one of those characters could probably land a paper isolating them in a good journal. Perhaps even more striking would be the identification of a locus leading one of the sterotyped behaviors of a working dog. Half of Dr. Ostrander's seminar 1111 years ago (hey, this is an informatics blog!) was video of border collies herding sheep -- and ever since I can't watch a border collie playing with a frisbee or playing with kids and think of it except in terms of herding.
Many other domesticated animals have a large number of interesting breeds, but never quite as varied as dogs. Dogs were simply bred for more roles than cats, pigs, horses, cows or rabbits -- leading the selection of a wider variety of traits.
Yes, dog genomics promises to dig out some interesting biology, to fetch new insights into the genetics of morphology and behavior. When it comes to the secrets of the mammalian genome, we must not let sleeping dogs lie.
Dogs are amazing products of human selection. Size, color, shapes of various body parts, and even behaviors are distinctive to particular breeds. The size range of adult dogs exceeds that of any other mammal, as wonderfully illustrated by the
cover of Science, as the issue announces the IGF1 locus as the major determinant of size in dogs.
This paper also illustrates how science can be a bit slow to get off the ground. About 15 years ago I heard a seminar from the senior author of this paper discussing the great promise of dog genetics to shed light on important medical and biological questions. In the meantime, there really haven't been much in the way of splashy dog genetics papers, though the community has been slowly building up a cache of tools. I think it is a reasonable expectation that this paper will be the head end of a series of papers unleashing the promise of the field.
After all, consider my diminutive assistant.
. If you line her up with a Scottish terrier, while they are about the same size they have little else in common in their basic shape. Amanda has the flat face characteristic of her tong (The Ancient and Honourable Order of the Shih Tzu), whereas the Scottie has a distinctive snout which marks his clan. Her tail could honestly mistaken for a feather duster, whereas the terrier's has a less severe curl and isn't fluffy. A Scottie has erect ears; a Shih Tzu's are floppy. Each one of those characters could probably land a paper isolating them in a good journal. Perhaps even more striking would be the identification of a locus leading one of the sterotyped behaviors of a working dog. Half of Dr. Ostrander's seminar 1111 years ago (hey, this is an informatics blog!) was video of border collies herding sheep -- and ever since I can't watch a border collie playing with a frisbee or playing with kids and think of it except in terms of herding.Many other domesticated animals have a large number of interesting breeds, but never quite as varied as dogs. Dogs were simply bred for more roles than cats, pigs, horses, cows or rabbits -- leading the selection of a wider variety of traits.
Yes, dog genomics promises to dig out some interesting biology, to fetch new insights into the genetics of morphology and behavior. When it comes to the secrets of the mammalian genome, we must not let sleeping dogs lie.
Tuesday, April 03, 2007
And then there were four
This weekend brought the news that in quick succession the last U.S. female veteran and last U.S. Navy veteran of World War I had died. Now only four veterans of World War I are known to reside in the U.S., three from the U.S. Army and one from the Canadian Army. Similar handfuls survive from the other participants. Despite its inevitability, it is striking when such a large cohort of people disappears. A huge chapter of human history loses all its living witnesses.
My own grandfather was a doughboy, though he never spoke about it. I have a few mementos of his service -- his helmet, a reproduction of the photo of his unit before it shipped out and a copy of his war diary lovingly transcribed by my mother from the disintegrating original. I am only one dereference away, but that is still a great distance.
World War I got scant attention in my grade school history classes -- a mention of the assassination which fermented it (which was probably the only mention ever of the Habsburgs!), a recitation of the events leading to U.S. entry, and perhaps an iconic picture of an American soldier in the Ardennes. The Armistice and the Paris peace talks would about round it out. Given the late entry of the U.S. and the still debated impact of its entry, and the fact that my history classes were universally parochial in their world view, it is not surprising.
On reflection, what is perhaps more striking is the minimal number of scientific or technological changes which are routinely traced to The Great War, particularly in contrast to the greater cataclysm it helped set up. While a number of innovations in human slaughter are routinely cited, about the only non-military influence I can immediately think of is the impact on aviation -- both by driving technical advances and by generating a large pool of pilots, who would later barnstorm across the U.S.
World War II on the other hand is permanently associated with a large number of technologies. Perhaps first on the list would be atomic energy, but radar and rocketry would be close behind. In the biomedical arena, WW2 caused a huge push forward in antibiotic production methods.
While the Genome Project seemed like big biology -- and it was, it was nothing in scale compared to the Manhattan Project or Apollo. Someday the last of these cohorts will leave this world. It may well pass unnoticed, as the prominence and certainty of military service are far beyond that of any civilian enterprise.
All of these individuals are of advanced age, considering that the war itself started 93 years ago this summer. What remarkable lives!
Sunday, April 01, 2007
Bits off the Wires
For almost as long as I can remember, I have been a compulsive reader. Our house had a daily paper and a number of periodicals, and I read many of them. Before my teens I was regularly reading two daily newspapers, as we subscribed to the one major Philadelphia daily and I delivered the other one. In college, I worked shelving periodicals, and so my breaks were often spent browsing magazines.
The Internet has of course expanded the reach of what I can access immensely. There are a number of regular sites I visit, but I also enjoy clicking through to things that look interesting. I use Gmail for my personal mail, and so my incoming mail triggers sidebar ads -- for example, if my mail mentions 'DNA', which isn't uncommon, there is at least one creationist site that routinely shows up. I also spend a lot of time Googling for useful information, which brings up all sorts of sidebar ads. Some are totally silly -- I can apparently buy DNA sequencers (and worn socks) on eBay, and others are varying degrees of odd. A few of the choicer items from recent searches are below.
An obscure English institute of learning convened a press conference in a small village to announce that a research team is close to identifying the gene responsible for the obscure genetic syndrome of 'squibism' -- sufferers apparently lack certain abilities this institution finds appealing. The item mentioned that it may be allelic to being a muggle, but I hadn't heard of that either. The spokesman mentioned that the institute is also investigating a number of unusual creatures capable of generating very high internal body temperatures, with possible applications in energy production or bioremediation. However, when pressed for details the spokesman vanished from the press conference.
A more frightening item concerns a precocious, but sinister, trio of children who are apparently playing around with genetically modifying a deadly fungus known as the Medusoid Mycelium. According to The Daily Punctillo, these Baudelaire siblings have apparently been associated with a series of unfortunate events, including arson and the loss of a research submarine. Luckily for all of us, a very dashing chap named Count Olaf has promised to track them down and separate them from their source of funds for these dastardly experiments. Given the facts presented, we should all have a Very Fervent Desire that this be accomplished as soon as possible.
Finally, I stumbled on a website for Samiam Biotechnology Inc., which is proposing to market foods based on chickens and pigs transgenic for green fluorescent protein. I always meant to try some modern biotech foods, but have never gotten the chance. However, this seems to be just a little too weird for me -- it's one thing to have food that is enhanced for nutrition or shelf life or flavor, but to modify its genes just to have fun eating under a black light? I think that's a bit much. No, I would not eat them on a boat, I would not eat them with a goat...
Friday, March 30, 2007
Trying to Gulp Through A Coffee Stirrer
I'm not a big coffee drinker -- indeed I come from a long line of not big coffee drinkers -- but I do often raid various coffee establishments for other goodies, and in the cold weather (perhaps behind us for a while) that includes hot cocoa.
Of course, greedily drinking a hot beverage can be the route to a host of unpleasant effects. Sometimes a straw makes sense, but many such places just have the little hollow plastic coffee stirrers. They might faintly resemble straws, but the exercise of trying to use one in that way is mostly an exercise in frustration, as the throughput just isn't sufficient.
I had a similar feeling today at work. It had occurred to me that the some data I wanted to explore was probably out there on the internet somewhere -- and indeed it is in a dozen or so 'boutique' databases. One I found had a nice prominent download link, and in short order the whole dataset was on my machine & parsed into the form I needed.
However, no such luck with any other database. They all have decent web front ends, but the last thing I want to do is browse the data one record at a time. I'm not even sure the precise data I want is in the database -- how many records should I browse before giving up? And since what I want is an atypical small subset of the data, it isn't surprising the web interface really doesn't support my query.
Anyone who curates data & makes it available deserves applause, and I hate to sound ungrateful. But could you please make a flatfile dump available? Someone might just want to use your data in a way you didn't imagine.
Thursday, March 29, 2007
454? How Roche!
Today's GenomeWeb bears the news that Roche Diagnostics is buying out 454 Life Sciences. Since Roche was previously the sole distributor of 454's sequencers and Curagen had announced their desire to sell the subsidiary, this is hardly a shocking development. But it is the third next generation sequencing company to be bought by an established player -- ABI slurped up Agencourt Personal Genomics and Illumina recently bought Solexa. So far, Affymetrix and Agilent have stayed out -- as has Nimblegen. There are plenty of other startup next generation sequencing shops out there, and certainly other candidates for acquirers. Roche, of course, got the clear current front runner, though it may be that the next wave of sequencer launches will close the gap quickly.
Whether these acquisitions are good for next generation sequencer development is an open question. On the one hand, these larger organizations bring deep pockets and substantial marketing expertise. But, there are plenty of pitfalls. For both ABI and Illumina, the new machines compete with their old machines -- smart companies see this as inevitable, but many companies completely botch the job due to internal conflicts (as amply documented by Clayton Christiansen in his books). It isn't encouraging that the Agencourt Personal Genomics technology is impossible to find on the ABI website.
It will also be interesting to see how long the 454 moniker lasts -- one hates to see pioneers go, but on the other hand I find naming a subsidiary after the accounting code tres gauche.
An interesting note in the GW item is that Roche was previously prohibited from marketing regulated diagnostics built on the 454 platform. Roche has previously tried to launch some molecular diagnostics -- the D word is after all in their name -- so this is a clear fit. On the other hand, a run on the 454 is reputed to be serious money, so they'll need to either find a very high value application (in a field notorious for antiquated, miserly reimbursement rules) or figure out a way to run lots of tests simultaneously. Given the rather long read lengths of the 454, one approach to the latter would be to use sequence tags near the beginning of the read to identify the original samples.
Another GW item describes some roundtable discussion at a recent meeting on next generation sequencing. The price for a genome in 2010 is still a big question, but a lot of bets are apparently in the $10K-$25K range. Some of the leaders in the field are taking a realistic view of the utility of such sequencers at such a price tag -- if you can scan the most informative SNPs for $1K, then why sequence? I'm guessing that other than a few pioneers (J.Craig is apparently resequencing his genome), there won't be a lot at those prices. On the other hand, cancer genomics is a natural fit, as each genome is different (indeed, each sample probably has many distinguishable genomes) and understanding all the fine molecular details will be valuable. SNP chips can estimate copy numbers, but not tell you how those pieces are stitched together nor find all the interesting mutations.
Even with the price at $1K, sequencing will certainly not be 'too cheap to meter'. Notions of sequencing a big chunk of the human population have appeal, but do we really want to blow another few billion dollars on human sequencing? On the other hand, as I've suggested before, other mammalian genomes may provide a lot of interesting biology for the buck (or bark). What are the most interesting unbagged genomes out there -- that sounds like the topic for another day's post...
Wednesday, March 28, 2007
Tiny Tug-of-War
I never got past introductory physics in college, particularly since I put off taking it until my senior year. Many of the basic concepts had shown up every so many years in grade school, but college really tied it together & for a brief time I could run the equations in my sleep. Lots of the problems involve springs and pulleys and other simple mechanical gadgets.
Last week's Nature contains a paper which is in the growing field of doing experiments on springs and other simple machines -- except here the gadgets are biomolecular machines, in this case the E.coli ribosome. The technologies are a bit fancier than what we had in grade school -- optical traps and such -- but in the end the desired measurements are similar -- what force does it take to balance (or overcome) a force within the molecular machine.
A huge book on my father's bookshelf was The Handbook of Chemistry and Physics, which had all sorts of tables of useful measured values and derived constants. I have the 1947 edition on my bookshelf, a present from one of my father's friends -- though I confess I've never done more than flip the pages of either one. There must be an electronic, molecular biological equivalent out there with the sort of data from this paper, but I don't know where it is. I could use it periodically -- I was recently trying to find rate and accuracy figures for RNA polymerase and the ribosome, and it isn't easy to do & I'm not sure I trust what I've found.
Thursday, March 22, 2007
Error Will Robison
After my post on the mental challenge of juggling multiple programming languages, I realized another reason I like to stick to a few: grokking the error messages.
In an ideal world the various messages kicked out from ill-formed or ill-performing code would always precisely and instantly finger the exact problem -- in which case the programming environment would just go fix them. Some programming languages do try to assist you a lot. For example, Perl often guesses that you really didn't mean to have a quoted string run over many lines, and thereby shows you where the long quote starts. Similarly, it will often suggest that a semicolon addition that might cure the problem.
But not always are the error messages on the mark -- sometimes the wrong quote is really a bit before where it points out, or a missing semi-colon is not the problem. Worse, when the Perl interpreter chokes on a program, it generally spits out one of two error messages: Out of Memory or Segmentation Fault. In either case one goes looking for an inadvertant infinite loop or endless recursion (the Perl debugger catches these quite often with a more informative message). One common Perl trap is the one letter deletion which converts nicely behaving code such as:
into
Another gotcha (or should I say, gotme) is the wrong loop end condition
My problems don't tend to call for much recursion, so when I get 100 levels in it must be a mistake. Most commonly it is due to a botched lazy initiation -- a scheme by which some complex object doesn't set up internal states until they are asked for. I do this a lot right now as I have objects representing complex data collections stored in a relational database, and it doesn't make time sense to slurp every last piece of data from the database when you only want a few. However, one must be careful:
My errors with R tend to fall into a small number of categories, and the error messages are generally informative. Out of memory means I really did blow out memory. Trivial syntax errors (changing the assignment <- to <= or =), passing nulls (or no data) to something which doesn't care for it, etc.
On the other hand, I'm glad that I don't do a lot of Oracle (SQL) programming, or at least a wide variety of it, because the error messages there are as clear as mud to me. Luckily, there is a small number of mistakes I make; probably 95% fall into : misspelling a table name or alias, misspelling a column name, letting Perl-isms slip in ($column), missing commas, and extraneous commas. The only that is SQL-specific is botching GROUP BY columns and functions. The only runtime errors I tend to get are either minor hiccups from database inconsistencies or queries that never seem to return because of a botched join.
It looks like I might have a real need to learn C#, which means reverting a bit of a decade (when I used C++). Learning the language is one thing; learning the hidden language of error messages always takes a lot longer
In an ideal world the various messages kicked out from ill-formed or ill-performing code would always precisely and instantly finger the exact problem -- in which case the programming environment would just go fix them. Some programming languages do try to assist you a lot. For example, Perl often guesses that you really didn't mean to have a quoted string run over many lines, and thereby shows you where the long quote starts. Similarly, it will often suggest that a semicolon addition that might cure the problem.
But not always are the error messages on the mark -- sometimes the wrong quote is really a bit before where it points out, or a missing semi-colon is not the problem. Worse, when the Perl interpreter chokes on a program, it generally spits out one of two error messages: Out of Memory or Segmentation Fault. In either case one goes looking for an inadvertant infinite loop or endless recursion (the Perl debugger catches these quite often with a more informative message). One common Perl trap is the one letter deletion which converts nicely behaving code such as:
while (/([A-Z])/g) { push(@array,$1); }
into
while (/([A-Z])/) { push(@array,$1); }
Another gotcha (or should I say, gotme) is the wrong loop end condition
for ($i=10; $i>0; $i++ { print "$i\n"; }. Again, the symptom tends to be running out of memory on a trivial task.
My problems don't tend to call for much recursion, so when I get 100 levels in it must be a mistake. Most commonly it is due to a botched lazy initiation -- a scheme by which some complex object doesn't set up internal states until they are asked for. I do this a lot right now as I have objects representing complex data collections stored in a relational database, and it doesn't make time sense to slurp every last piece of data from the database when you only want a few. However, one must be careful:
sub getId
{
my ($this)=@_;
unless (defined $this->{'foo'})
{
$this->createFoo();
}
}
sub createFoo
{
my ($this)=@_;
my $id=$this->getId(); # round-and-round we go!
}
My errors with R tend to fall into a small number of categories, and the error messages are generally informative. Out of memory means I really did blow out memory. Trivial syntax errors (changing the assignment <- to <= or =), passing nulls (or no data) to something which doesn't care for it, etc.
On the other hand, I'm glad that I don't do a lot of Oracle (SQL) programming, or at least a wide variety of it, because the error messages there are as clear as mud to me. Luckily, there is a small number of mistakes I make; probably 95% fall into : misspelling a table name or alias, misspelling a column name, letting Perl-isms slip in ($column), missing commas, and extraneous commas. The only that is SQL-specific is botching GROUP BY columns and functions. The only runtime errors I tend to get are either minor hiccups from database inconsistencies or queries that never seem to return because of a botched join.
It looks like I might have a real need to learn C#, which means reverting a bit of a decade (when I used C++). Learning the language is one thing; learning the hidden language of error messages always takes a lot longer
Monday, March 19, 2007
Personalized Medicine: The long slog
Personalized medicine is a wonderful concept: instead of lumping huge groups of patients with similar symptoms together to be treated with a standard regimen, therapy would be tailored to each patient based on the specifics of their disease. This fine-grained diagnosis would be dtermined using the fruits of the human genome project.
In some sense this is simply an attempt to accerate the long-term trend in medicine of subdividing diseases. From four humors we have moved to a myriad of diseases. In a more specific sense, consider leukemia. In the 1940's, when my paternal grandmother succumbed to this disease, there were (as far as I can tell) less than a half dozen recognized leukemia subtypes; these days there are certainly over one hundred. This is not idle splitting; each disease has its own diagnostic hallmarks, treatment strategies, and outcome expectations. Great (but not universal) success has been achieved with childhood leukemias, whereas some other leukemias are still very grim sentences.
To realize the dream of personalized medicine is going to require a lot of hard work, both in the lab and in the clinic. I'm going to go into some detail on one such endeavor, one which I am very familiar with because I was peripherally involved with it. Now, in the interest of full disclosure, it must be stated that I still retain a small financial interest in my former employer, Millennium Pharmaceuticals, and that several of the authors are good friends. However, it should also be pointed out that while Millennium once trumpeted every baby step towards personalized medicine, the electronic publication of this story engendered no press release. If the company thinks it can't perk up its share price with the story, there is faint reason to think I can.
Multiple myeloma is a malignancy of the antibody secreting cells, the plasma B cells. Two famous victims are the columnist Ann Landers and actor Peter Boyle; a well-known long-term survivor is former vice presidential candidate Geraldine Ferraro. Cancers are often loosely broken into two categories: "liquid" tumors such as leukemias and solid tumors. Myelomas occupy the mushy middle: while they are derangements of the immune system like leukemias, myelomas can form distinct tumors (plasmacytomas) in the body. A hallmark of the disease is bone destruction around the tumors; patients' X-rays can have a 'swiss-cheese' appearance.
Myelomas are a devastating disease, but also occupy an important place in biotech history. Because myelomas sprout from a single deranged antibody-secreting cell, the blood (and ultimately urine) of patients becomes full of a single antibody, the M-protein (also known historically as a Bence-Jones protein). A flash of inspiration led Koehler & Milstein to realize that if they could have that antibody be one of their choosing, then a limitless source of a specific antibody could be at hand. The monoclonal antibody technology which they invented led to a host of useful reagents and tools, including home pregnancy kits. The last decade has finally seen monoclonal antibodies become important therapeutic options, particularly in cancer, and a number are being tried on myeloma: a complete circle.
The drug of interest here is not an antibody but rather a small molecule: bortezomib, tradename Velcade and known in the older literature as MLN341, LDP341 or PS341. Bortezomib works like no other drug on the market: it blocks the action of a large complex called the proteasome. A key normal function of the proteasome is to serve as the cells main protein disposal system, chewing old or broken proteins back into amino acids. Destruction of proteins by the proteasome can also be a regulated process and appears to be a component of many genetic processes.
Bortezomib has been tried as a therapeutic agent, either alone or in concert with other drugs, against a wide array of tumors. It has disappointed often, still tantalizes in some areas, and has received FDA approval for two malignancies: multiple myeloma and another B-cell malignancy called mantle cell lymphoma.
Early in the clinical trial process Millennium decided to build a personalized medicine component into the main Velcade trials in multiple myleoma. The justification for this was a mix of different ideas: including a desire to show results in personalized medicine, a potential to use the personalized medicine element to support FDA approval should trial results be equivocal, an opportunity to understand why myelomas are sensitive to proteasome inhibition.
The design was both simple and audacious: in each trial patients would be asked to supply a bone marrow biopsy for analysis by RNA profiling, which can examine the levels of each gene's mRNA. It sounds simple; in practice this would use a cutting edge technology (RNA profiling) notorious for sensitivity to sample processing. It would also be the first use of such technology in a prospective clinical trial; prior publications had either used archived samples or new samples from available patient populations. Protocols would have to be devised, staff trained at each clinical center in a multi-center trial.
The results can now be seen in Blood as Mulligan et al. You will need paid access to the journal to read the details, which most large academic libraries should have. Also, the sponsors of Blood (American Society of Hematologists) have some mechanism for patient access -- and eventually (I think it is 6 months) they make everything free. The data supplement and methods supplement are free.
Table 1 gives you some hint why few companies will be eager to invest in this kind of study again, as it details how many samples actually made it to the analysis. One can envision the path from trial to data ready to analyze as a pipeline of many steps, each of which is leaky. Patients must consent, the myleoma fraction purified, RNA captured, arrays analyzed and finally useful survival data obtained. Patient consent refusals (or later paperwork deficiencies), poor samples, patients lost to follow-up, etc. eat into the starting material. Even good clinical luck can be problematic: one of the key bortezomib trials was halted early because the drug was clearly working better than the control drug. This was great news for patients, who needed (and still need) more treatment options, and great news for the company, which could more quickly obtain approval to sell the drug. But it both deprived the personalized medicine study of anticipated patients and muddied the waters on many others. For example, samples had been obtained from control arm patients, but now many of these patients were crossing over to bortezomib and were no longer useful controls.
How leaky was the pipeline? Four clinical studies had RNA profiling components (another complication; each study was on a different trial population, with different disease characteristics). Looking at evaluable survival (meaning the patient stayed in the study long enough to figure out if the drug helped them live longer or not): 13%, 22%, 23% and 22% of patients from the 4 trials (024, 025, 039 & 040 respectively) had data for evaluation.
On the other end, many studies were accumulating information that myleoma has many genetic subtypes: perhaps at least seven or so major ones, and many of these can be further subdivided. For example, one major translocation driving myleoma involves a gene called MMSET. In a subset of these patients, a second gene (FGFR3) is also activated by the translocation. Many other classical clinical measures are used by clinicians, such as albumin and CRP levels. A very interesting question would be whether bortezomib had greater or lesser activity in any of the subtypes (or sub-subtypes); but with the ferocious sample attrition, the sample numbers just aren't great enough to be able to draw conclusions. This also illustrates the power & problem of RNA microarrays: you can look at tens of thousands of genes, allowing you to find patterns with few preconceived biases. But, you are looking at tens of thousands of genes, so the multiple testing problem is very acute.
The other thing most frustrating about this study, as in a large number of RNA profiling studies, is that there is no Eureka! moment coming from the data. Gene sets were successfully identified which can predict response or survival, but what do they mean? The hope that RNA profiling would provide the Cliff's Notes to a tumor is a hope rarely realized; instead the tumor reveals a nearly inscrutable scrawl. The study succeeded scientifically, but commercially it was not a contributor.
This will probably be more the norm than the exception in the quest for personalized medicine. Huge investments will need to be made in large clinical studies, many of which won't bear fruit, at least immediately. Combined with other myleoma studies, the Mulligan et al study will enhance our knowledge of myleoma. The execution of the study provides a roadmap for other such studies. New technologies are available which weren't when these studies began. In particular, for cancer one might opt for DNA profiling to map the underlying genetic makeup of the tumor (greatly hashed), rather than RNA. While RNA is where the action really is, DNA is much more stable and therefore may lead to results more consistent between clinical sites. And once in a while, a study might just have results that have oncologists running through the streets, making the whole exercise worthwhile.
Wednesday, March 14, 2007
Cancer Kinases
Last week's Nature had a big paper from the Sanger surveying human protein kinase gene hunting for somatic mutations in cancer. The paper (and a News&Views item; alas, both require a subscription) has deservedly received a lot of press coverage, but a few notes.
First, it is important to underline that this is a first discovery step which associates these mutations with cancer, but it certainly can't guarantee that they are involved. Tumors generally have very battered genomes; indeed, the study noted more mutations in tumors likely to have undergone extensive mutagenesis (defects in DNA repair, smoking-related lung tumors, melanomas from skin exposure, tumors in patients treated with mutagenic oncologic drugs). A useful filter is to compare the ratio of synonymous to non-synonymous mutations, that is those mutations which do not change the amino acid coded in the message vs. those that do. Synonymous mutations should be (to the first approximation) not selected against, so they can be used to estimate the background mutation rate. If a non-synonymous mutation is seen more often than expected, it is inferred to have been selected as advantageous.
One interesting side observation is that in some tumors there is an excess (vs. random chance) of mutations at TC / GA dinucleotides (or TpC / GpA as written -- a common convention to specify that this means T followed by C and not any dinucleotide containing T and C). Such a pattern was not observed in germline (normal) samples from the same patients nor has it been observed previously, suggesting a tumor-specific mutational process.
Protein kinases are an obvious set to look at because so many are already known to implicated in cancer and drugs targeting kinases have already been found useful in the clinic. Indeed, this week the FDA gave the first approval for Tykerb, another small molecule drug targeting oncogenic kinases. The kinases found in the study include many kinases already well implicated in disease. For example, the same group had previously found BRAF mutated in many melanomas. I've discussed STK6 (AuroraA) in this space previously, and STK11 (LKB1) is a well studied tumor suppressor. But there are some interesting surprises. For example, in the list of the top 20 kinases ranked by probability of carrying a cancer driver mutation, there appear to be at least two kinases that are essentially completely uncharacterized in the public literature, MGC42105 & FLJ23074. Another interesting hit is the top one in the list: titin, a protein that hugely deserves its own post. Titin's functions in muscle are well characterized, but a role in cancer would appear to be new. A mutation in KSR2 which resembles kinase activating mutations in other kinases is interesting, as KSR2 has at least sometimes been thought to be an inactive pseudokinase. AURC, whose role in anything remains controversial, shows up with a mutation in a key part of the ATP-binding pocket (P-loop).
There will be a lot of work to actually nail down the role (or lack thereof) of these kinase mutations in cancer. Many other experiments, such as RNAi, have been targeting kinases to try and identify roles in cancer. Most of the mutations observed here were seen in only a few tumors, so there will be lots of work to screen more tumor samples and important cell lines for these mutations. Finally, there are a lot of other genes and gene families (e.g. small GTPases) worth looking at.
However, this is all still very expensive (though the total sequence data, while huge by most standards -- 274Mb of final sequence, pales next to Venter's metagenomics cruise of 6.3Gb). An important question is to what degree should research dollars be invested in these studies vs. other important functional studies (such as RNAi & conditional mouse models, to name just 2). While new sequencing technologies will bring down the costs of large scale sequence scanning, the cost will not go to zero. Balancing the approaches will remain a great challenge for the cancer research community.
Tuesday, March 13, 2007
Sailing the Genomes Blue
Today's Wall Street Journal had an item on Craig Venter's new publication in PLoS Biology describing the collection and metagenomic sequencing of seawater from around the world. You'll need to have paid access to the WSJ, or find a print copy (my access), or perhaps it will show up on a free newspaper site at some point (many WSJ articles do via the wire services). Further information is available on the expedition's website, including pictures of their sailboat Sorcerer II.
The raw numbers are amazing: 6.3 Gbp of raw data -- or about 1.5 human genome equivalents -- and all apparently by 'old-fashioned' fluorescent Sanger sequencing. Samples were collected at regular intervals along the sailing route
There's a lot in the paper, and I won't pretend to have read all of it. One interesting bit is what the authors call 'extreme assembly'. Whereas most genome assembly schemes attempt to minimize the probability of getting chimaeric assemblies (with data glommed together that should be apart), this approach tries to get as big an assembly as possible -- as long as 900Kb from this dataset. While chimaeras are expected (and found), the hope is that you can untangle the knots later but that these extreme assemblies will be useful in collecting sequences together that should go together.
One other nice bit: in addition to deposition at NCBI, the data & tool set will be made freely available at a site called CAMERA. One of my long-held idealistic beliefs in the genome project & bioinformatics is that it can be a great leveler of educational institutions (or more properly, a great boost for many smaller schools). With hardware which is increasingly cheap & ubiquitous, any undergraduate (or high school student!) can do interesting analyses using tools and data which are freely accessible. As an undergraduate, our budget for sequencing was about one kit per semester (and these were the pre-ABI days -- we're talking radioactive dideoxy here) -- and with a little bad luck we never got any useful data. I dabbled with public sequence data then -- but how little there was. Now, an undergraduate funded far worse than I was can have an endless supply of explorations.
The WSJ item brought out one interesting incident: at one point Venter and his crew were apparently placed under house arrest in a Pacific island nation (I forget which one; it was in the article). Treaties on bioprospecting give nations to the right to regulate such activities in their territorial waters, and Venter apparently didn't have the correct permits. Of course, the seawater bugs are probably rather deficient in critical documents such as passports, nor do I expect they swear allegiance to any nation.
Venter has, of course, obtained the career status many claim to dream of (particularly in the context of mega-lottery winnings): he is independently wealthy & gets to combine his favorite leisure activity with further promotion of his scientific interests. Color me several shades of green.
Monday, March 12, 2007
You say tomato, I say $tomato
When I first started programming thirty or so years ago, my choice of language was simple: machine code or bust. I didn't like machine code much, so I never wrote very much. A pattern, however, was established which would be maintained for a long time. A limited set of computer languages would be available at any one time, and I would pick the one that I liked the best and work solely in that. Machine code gave way to assembler (never mastered) to BASIC to APL to Pascal. Transitions were short and sweet; once a better language was available to me, I switched completely. A few languages (Logo, Forth, Modula 2) were contemplated, but never had the necessary immediate availability to be adopted.
A summer internship tweaked the formula slightly -- at work I would use RS/1, because that's what the system was, but at home I stuck to Pascal. For four years of college this was the pattern.
Grad school was supposed to mean one more shift: to C++. However, soon I discovered the universe of useful UNIX utility languages, and sed and awk and shell scripts started popping up. Eventually I discovered make, which is a very different language. A proprietary GUI language based on C++ came in handy. Prolog didn't quite get a proper trial, but at least I read the book. Finally, I found Perl and tried to focus on that, but the mold had been broken -- and for good measure I wrote one of the worlds first interactive genome viewers in Java. My thesis work consisted of an awful mess of all of these.
Come Millennium, I swore I would write nothing but Perl. But soon, that had to be modified as I needed to read and write relational databases, which requires SQL. Ultimately, I wanted to do statistics -- and these days that means R.
There are a number of computer language taxonomies which can be employed. For example, with the exceptions of make, SQL (as I used it) and Prolog all of these languages are procedural -- you write a series of steps and they are executed. The other three fit more of a pattern of the programmer specifying assertions, conditions or constraints and the language interpreter or compiler executes commands or returns data according to those specifications.
Within the procedural languages, there is a lot of variation. Some of this represents shared history. For example, C++ is largely an extension of C, so it shares many syntactic features. Perl also borrowed heavily from C, so much is similar. R is also loosely in the C syntax family. All of these languages tend to be terse and heavily use non-alphabetic characters. On the other hand, SQL is intrinsically loquacious.
The fun part is when you are trying to use multiple languages simultaneously, as you must keep straight the differences & properly shift gears. Currently, I'm working semi-daily in Perl, SQL and R, and there is plenty to catch me up if I'm napping. For example, many Perl and R statements can interchange single and double quotes freely -- as long as you do so symmetrically; SQL needs single quotes around strings.
Perl & R use the C-style != for inequality; SQL is the older style <> and in paralled Perl & R use == for equality whereas SQL uses a single = -- and since a single = in Perl is assignment, forgetting this rule can lead to interesting errors! R is a little easier to keep straight, as assignment is <- . R and Perl also diverge on $ -- for Perl it precedes every single value (scalar) variable, whereas in R it specifies a column of a table. I haven't done C++ or Java for over ten years, but my mind still wants to parse an R variable foo.bar as bar is a member of class instance foo (perhaps because that's the SQL idiom as well), but in R the period is just another legal character for composing a name -- and in Perl it's yet another syntax ( ->{'key'} ) to access the members of a class.
While I know all the rules, inevitably there is a mistake a day (or worse an hour!) where my R variables start growing $ and I try to select something out of my SQL using != . Eventually my mind melts down and all I can write is:
which doesn't work in any language!
A summer internship tweaked the formula slightly -- at work I would use RS/1, because that's what the system was, but at home I stuck to Pascal. For four years of college this was the pattern.
Grad school was supposed to mean one more shift: to C++. However, soon I discovered the universe of useful UNIX utility languages, and sed and awk and shell scripts started popping up. Eventually I discovered make, which is a very different language. A proprietary GUI language based on C++ came in handy. Prolog didn't quite get a proper trial, but at least I read the book. Finally, I found Perl and tried to focus on that, but the mold had been broken -- and for good measure I wrote one of the worlds first interactive genome viewers in Java. My thesis work consisted of an awful mess of all of these.
Come Millennium, I swore I would write nothing but Perl. But soon, that had to be modified as I needed to read and write relational databases, which requires SQL. Ultimately, I wanted to do statistics -- and these days that means R.
There are a number of computer language taxonomies which can be employed. For example, with the exceptions of make, SQL (as I used it) and Prolog all of these languages are procedural -- you write a series of steps and they are executed. The other three fit more of a pattern of the programmer specifying assertions, conditions or constraints and the language interpreter or compiler executes commands or returns data according to those specifications.
Within the procedural languages, there is a lot of variation. Some of this represents shared history. For example, C++ is largely an extension of C, so it shares many syntactic features. Perl also borrowed heavily from C, so much is similar. R is also loosely in the C syntax family. All of these languages tend to be terse and heavily use non-alphabetic characters. On the other hand, SQL is intrinsically loquacious.
The fun part is when you are trying to use multiple languages simultaneously, as you must keep straight the differences & properly shift gears. Currently, I'm working semi-daily in Perl, SQL and R, and there is plenty to catch me up if I'm napping. For example, many Perl and R statements can interchange single and double quotes freely -- as long as you do so symmetrically; SQL needs single quotes around strings.
Perl & R use the C-style != for inequality; SQL is the older style <> and in paralled Perl & R use == for equality whereas SQL uses a single = -- and since a single = in Perl is assignment, forgetting this rule can lead to interesting errors! R is a little easier to keep straight, as assignment is <- . R and Perl also diverge on $ -- for Perl it precedes every single value (scalar) variable, whereas in R it specifies a column of a table. I haven't done C++ or Java for over ten years, but my mind still wants to parse an R variable foo.bar as bar is a member of class instance foo (perhaps because that's the SQL idiom as well), but in R the period is just another legal character for composing a name -- and in Perl it's yet another syntax ( ->{'key'} ) to access the members of a class.
While I know all the rules, inevitably there is a mistake a day (or worse an hour!) where my R variables start growing $ and I try to select something out of my SQL using != . Eventually my mind melts down and all I can write is:
select tzu->{'name'},shih$color from $shih,$tzu where shih.dog==tzu.dog
which doesn't work in any language!
Subscribe to:
Posts (Atom)